What Is a Good AI Resolution Rate? Benchmarks From 195 Real Deployments
Everyone asks "what's a good AI resolution rate?" and gets a hand-waved number. We pulled real data from 195 deployments across 38 vendors. Here's the truth.
Summarize with AI
If you have ever asked what a good AI resolution rate is, the answer you found was almost certainly someone's marketing number or a hand-wave. I've spent enough time in customer support dashboards to know the quoted number and the lived number are rarely the same. So we did the work nobody else has published.
We pulled every named AI resolution stat we could find across the customer-support industry, normalized them into one comparable number, and added our own deployment data on top.
The short answer is that the field median sits around 70%. The longer answer is the one that actually helps you: that 70% hides almost everything that matters.
Which metric a vendor is counting, the industry the AI works in, and how much effort went into the setup all swing it hard. Company size, the thing people assume drives it, barely moves the needle.
I'm Mike, co-founder of My AskAI. We run AI customer service for 200+ ecommerce and SaaS businesses, our agents have resolved over 1,000,000 tickets, and our rolling resolution rate sits at 72%+ across the customer base. This report is built from that vantage point, plus 250 published competitor stats, so you can benchmark honestly instead of against a billboard.
What is a good AI resolution rate?
Across 195 real deployments and 38 vendors, the median AI resolution rate is 70%. Half the field sits between 56% (the 25th percentile) and 80% (the 75th percentile). The full range runs from 15% at the bottom to 98.3% at the top.
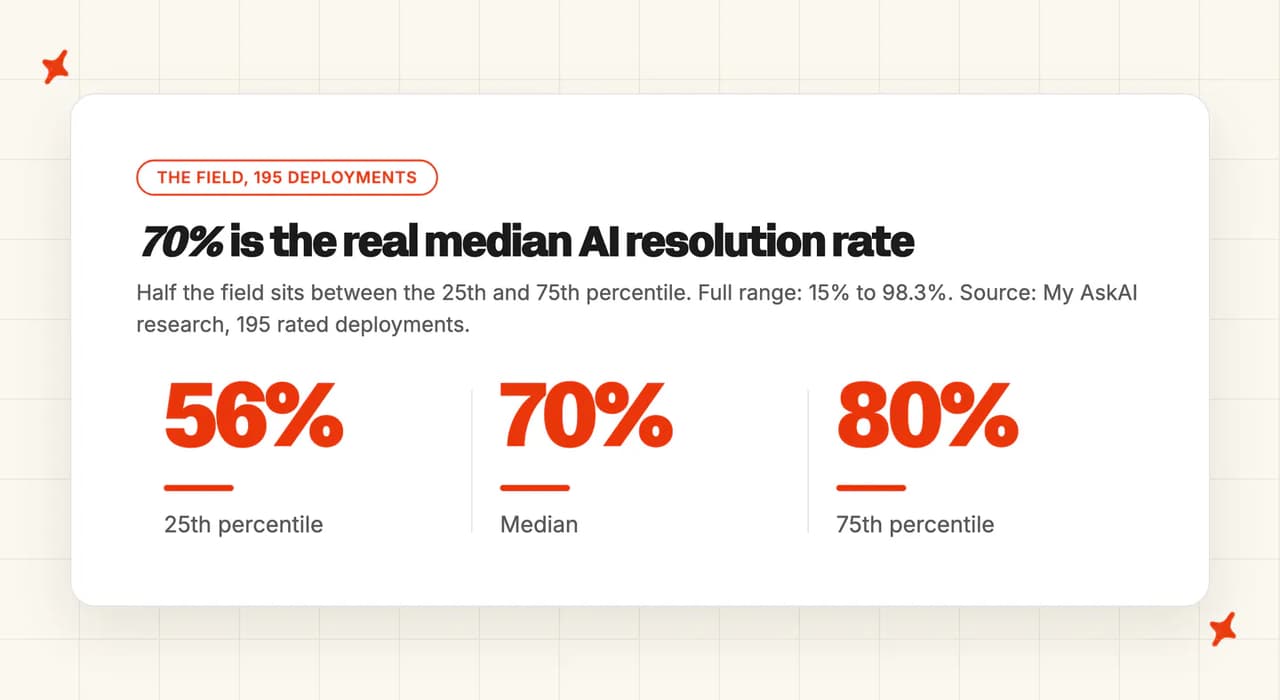
That 70% line is remarkably stable. The competitor-only field lands on a 70% median too (mean 66.5%), and our own customer base averages 72%, a little above it. When a number shows up this consistently across hundreds of independent deployments, it is a real center of gravity you can trust.
Two caveats before you read another chart. The competitor figures are self-selected, because a vendor publishes its wins rather than its average customer, so the true field average is probably a touch below this median.
The headline number also normalizes how the percentage is calculated while leaving each vendor's definition alone. That definitional gap is the single biggest reason quoted rates vary so wildly.
How we built this dataset
The dataset behind this report is 278 stat rows: 250 published competitor figures plus 28 of our own deployments. Those competitor figures span 38 vendors, from the big AI-agent names (Intercom Fin, Zendesk AI, Salesforce Agentforce, Decagon, Sierra, Ada, Gorgias) to specialist ecommerce and helpdesk players (Tidio, Maven AGI, Yuma, DigitalGenius). Of the 278 rows, 195 carry a clean, comparable AI-handling rate; the rest are CSAT, speed, or cost numbers we deliberately left out.
Each row records the vendor, the named customer where there is one, the verbatim stat, the metric family (resolution, automation, deflection, containment, self-serve, or one-touch), and enriched company data for industry, revenue band, and employee band. We then reduced each row to one clean rate: the headline percentage of contacts the AI handled. We excluded relative deltas like "45% fewer tickets", pure CSAT, and speed stats, because they answer a different question.
It is a point-in-time snapshot from May 2026, and I'll refresh it as the field moves. Resolution rates rise as models and setups improve, so treat these as today's baseline. The numbers will climb.
What actually moves a resolution rate
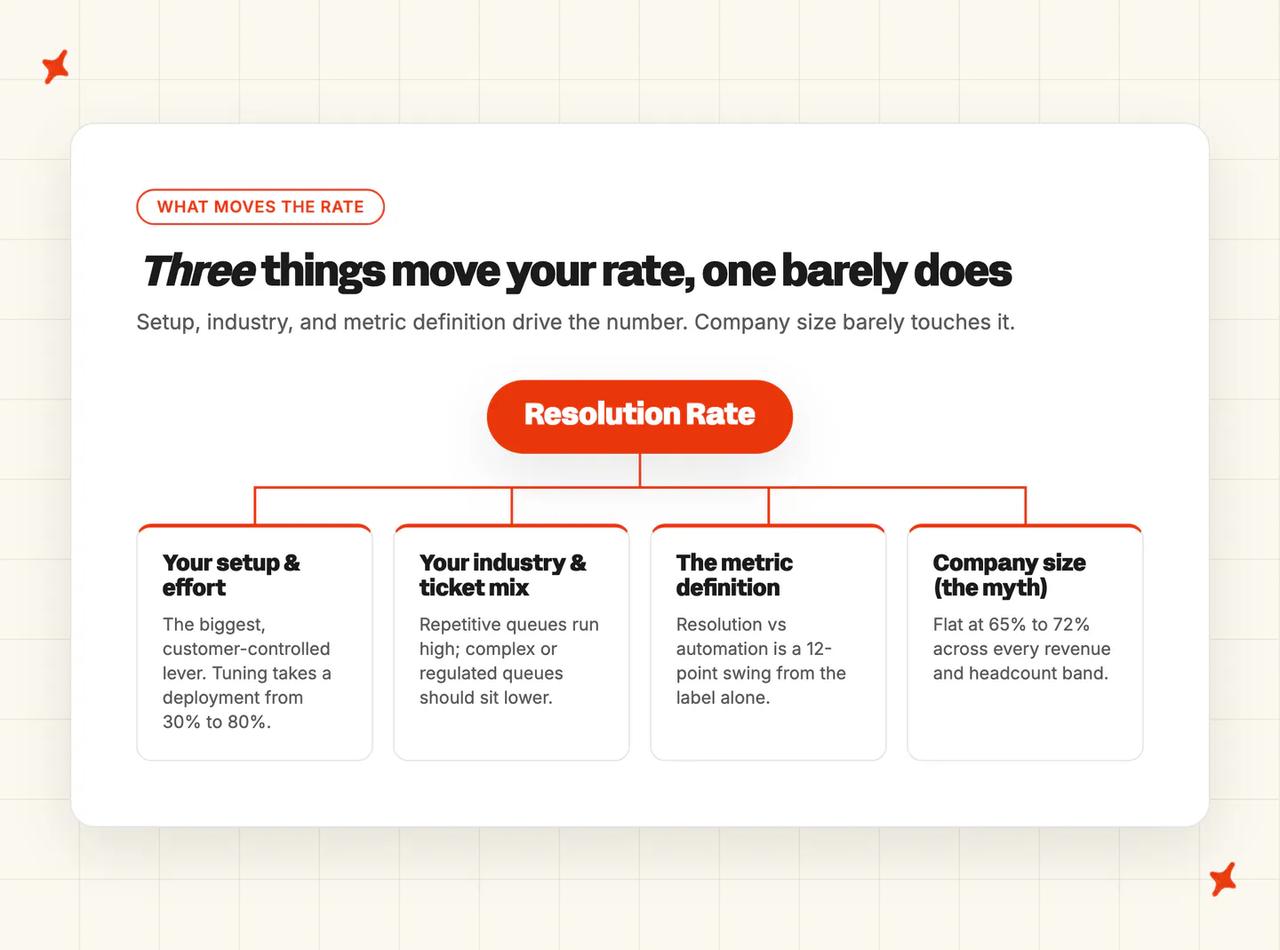
Here is the framework I keep coming back to, and it matters more than the headline number. Three things move your resolution rate, in this order of impact, and one thing everyone assumes matters turns out to be close to noise.
Lever 1: your setup and effort
This is the biggest lever, and it sits almost entirely in your hands. Knowledge coverage, connected APIs and tools, and tuned escalation rules are what separate a 30% deployment from an 80% one.
In our experience, most of what makes a resolution rate climb is work the customer does. The vendor's model and architecture help at the margin, and the bulk of the lift comes from your own setup. We have watched the same product go from 24% to 80% on one account through setup changes alone.
Lever 2: your industry and ticket mix
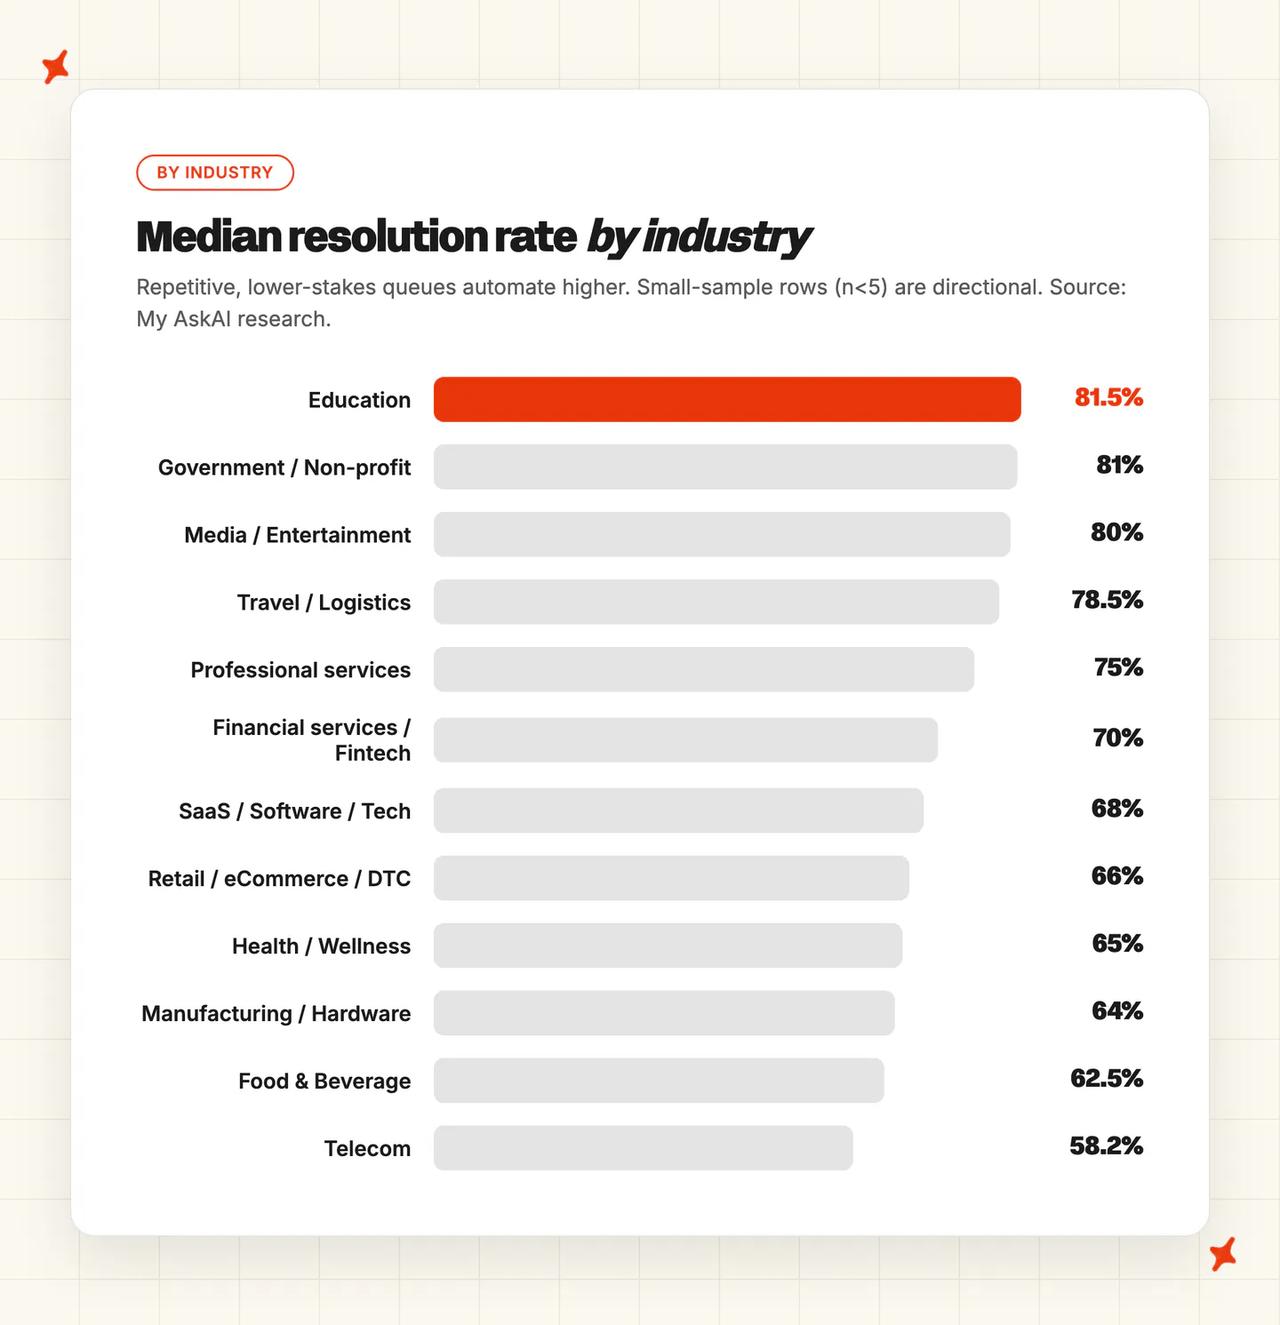
Some queues are simply more automatable than others. Education and travel queues run high, with medians above 78%, because the questions repeat. Telecom, manufacturing, and retail sit lower because the tickets are messier or higher-stakes.
A "low" rate in a complex queue can be the correct outcome, because more of those tickets genuinely should reach a person (and we'd argue that is the AI working as intended).
Lever 3: the metric definition
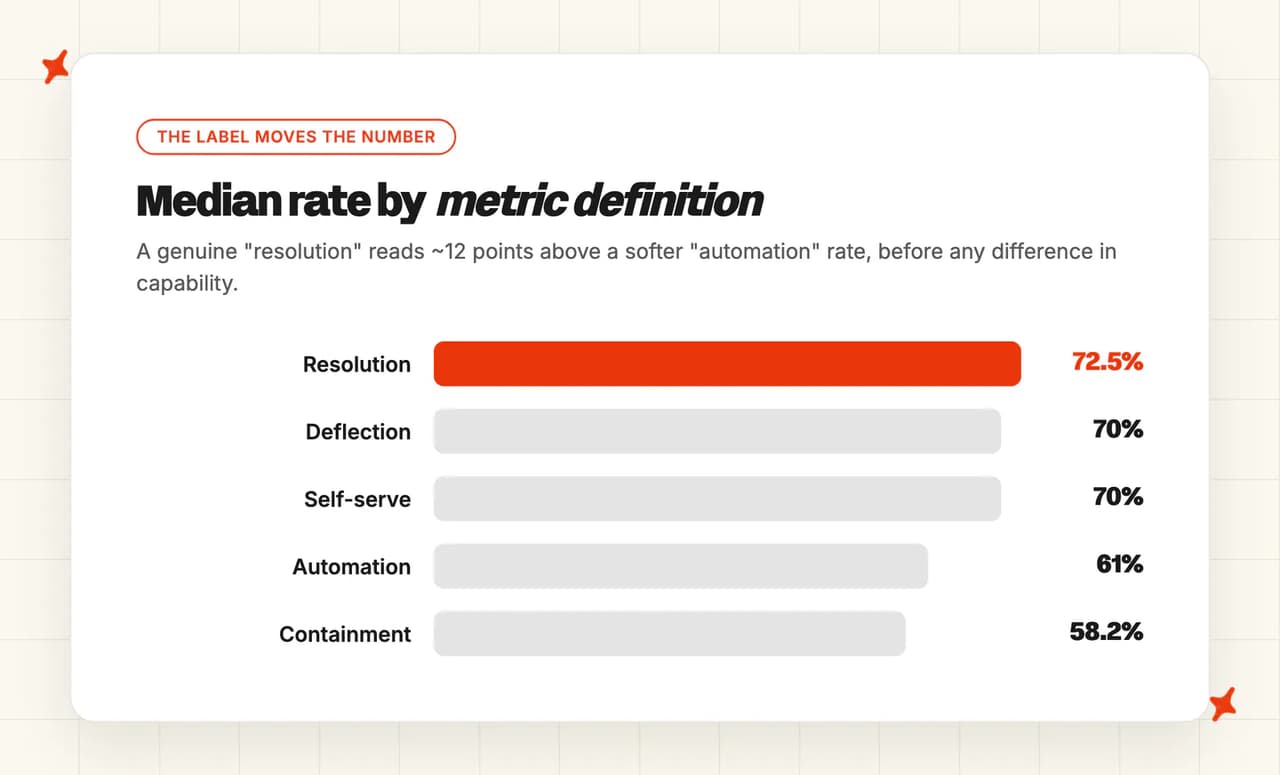
Before you compare two vendors, check what each one counts, because I've watched this trip up sharp buyers more than once. A genuine resolution metric carries a 72.5% median, and a softer automation metric carries 61%. That is a 12-point swing created by the label alone, before any difference in capability.
The myth: company size
People assume bigger companies get better (or worse) automation. They don't. Median rates stay in a flat 65% to 72% band across every revenue and employee tier we measured.
Size is close to noise. Setup and industry are the signal.
The full breakdown
This is the part to bookmark. Here is every way we can cut the data.
Read each median next to its sample size (n), because the small cells are only directional. Think of these as spreads of what the market reports rather than a ranking of who is best.
By metric type
The metric label is the first thing to normalize, because it moves the number more than anything else on this page.
| Metric family | n | Min | P25 | Median | Mean | P75 | Max |
|---|---|---|---|---|---|---|---|
| Resolution | 108 | 20 | 63.2 | 72.5 | 70.5 | 81.8 | 95 |
| One-touch / FCR | 3 | 60 | 60 | 75 | 75.7 | 92 | 92 |
| Deflection | 17 | 15 | 62.5 | 70 | 67.8 | 82.5 | 92 |
| Self-serve | 9 | 30 | 35 | 70 | 61.6 | 83.8 | 98.3 |
| Automation | 52 | 15 | 45 | 61 | 59.8 | 78 | 90 |
| Containment | 6 | 30 | 41.2 | 58.2 | 55.2 | 70 | 70 |
A vendor reporting "61% automation" and a vendor reporting "72% resolution" may be doing equally good work. The words measure different points on the customer journey. (We pulled apart exactly how these terms differ, and which one to report on, in our breakdown of containment, deflection and resolution.)
By industry
Industry is the second-strongest predictor. The spread from top to bottom is wide, and it tracks how repetitive and low-stakes the typical ticket is.
| Industry | n | Min | P25 | Median | Mean | P75 | Max |
|---|---|---|---|---|---|---|---|
| Education | 8 | 50 | 71.2 | 81.5 | 79.9 | 93.8 | 94 |
| Government / Non-profit | 3 | 75 | 75 | 81 | 80 | 84 | 84 |
| Media / Entertainment | 9 | 26 | 64.5 | 80 | 73.3 | 88 | 91.4 |
| Travel / Transport / Logistics | 10 | 40 | 72.2 | 78.5 | 75.6 | 86.8 | 87 |
| Professional services | 3 | 20 | 20 | 75 | 59 | 82 | 82 |
| Financial services / Fintech | 30 | 15 | 59.8 | 70 | 68.2 | 84 | 95 |
| SaaS / Software / Tech | 41 | 15 | 58 | 68 | 67.4 | 80 | 98.3 |
| Retail / eCommerce / DTC | 43 | 21 | 50 | 66 | 64.8 | 77 | 95 |
| Health / Wellness | 19 | 30 | 56 | 65 | 63.1 | 75 | 88 |
| Manufacturing / Hardware | 15 | 35 | 43 | 64 | 60.4 | 75 | 86 |
| Food & Beverage | 6 | 20 | 23 | 62.5 | 57.8 | 88.5 | 90 |
| Telecom | 2 | 57.5 | 57.5 | 58.2 | 58.2 | 59 | 59 |
| Other / Unclassified | 6 | 37 | 39.2 | 47.5 | 58.5 | 89.2 | 90 |
Benchmark against your own industry row rather than the global median. A 66% rate is below average for education and above average for retail. (Government, professional services, and telecom have small samples, so read those as directional.)
By company revenue
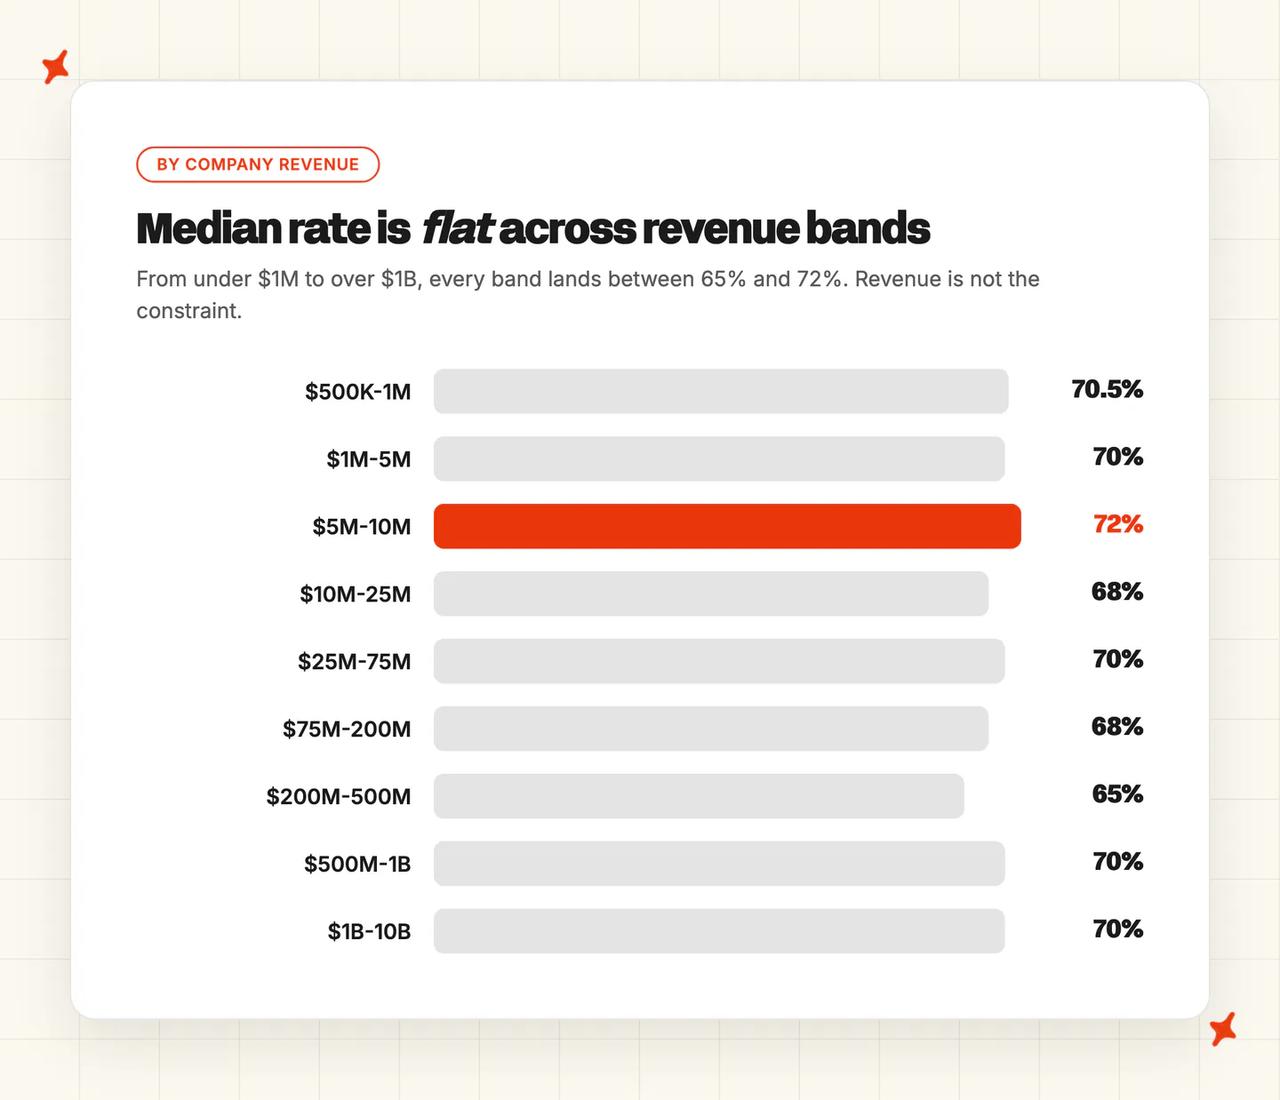
Now the myth-busting starts. If size drove resolution, you would see a clear slope down this table (we looked hard for one). You don't.
| Annual revenue | n | Min | P25 | Median | Mean | P75 | Max |
|---|---|---|---|---|---|---|---|
| $500K-1M | 10 | 15 | 40 | 70.5 | 63 | 85.2 | 87 |
| $1M-5M | 13 | 24 | 48.5 | 70 | 66.5 | 86.5 | 94 |
| $5M-10M | 21 | 40 | 59 | 72 | 70 | 80.5 | 95 |
| $10M-25M | 38 | 15 | 56.8 | 68 | 65.8 | 82.5 | 94 |
| $25M-75M | 29 | 20 | 52.5 | 70 | 68 | 84.5 | 93 |
| $75M-200M | 25 | 20 | 47.5 | 68 | 62.7 | 78 | 98.3 |
| $200M-500M | 15 | 26 | 45 | 65 | 59.2 | 74 | 80 |
| $500M-1B | 13 | 60 | 65 | 70 | 71.8 | 78.5 | 87 |
| $1B-10B | 13 | 50 | 60.5 | 70 | 70.2 | 80 | 92 |
Every band lands between 65% and 72%. A half-million-dollar startup and a billion-dollar enterprise hit roughly the same median. Revenue is not your constraint.
By company size (employees)
The employee view tells the same story even more flatly.
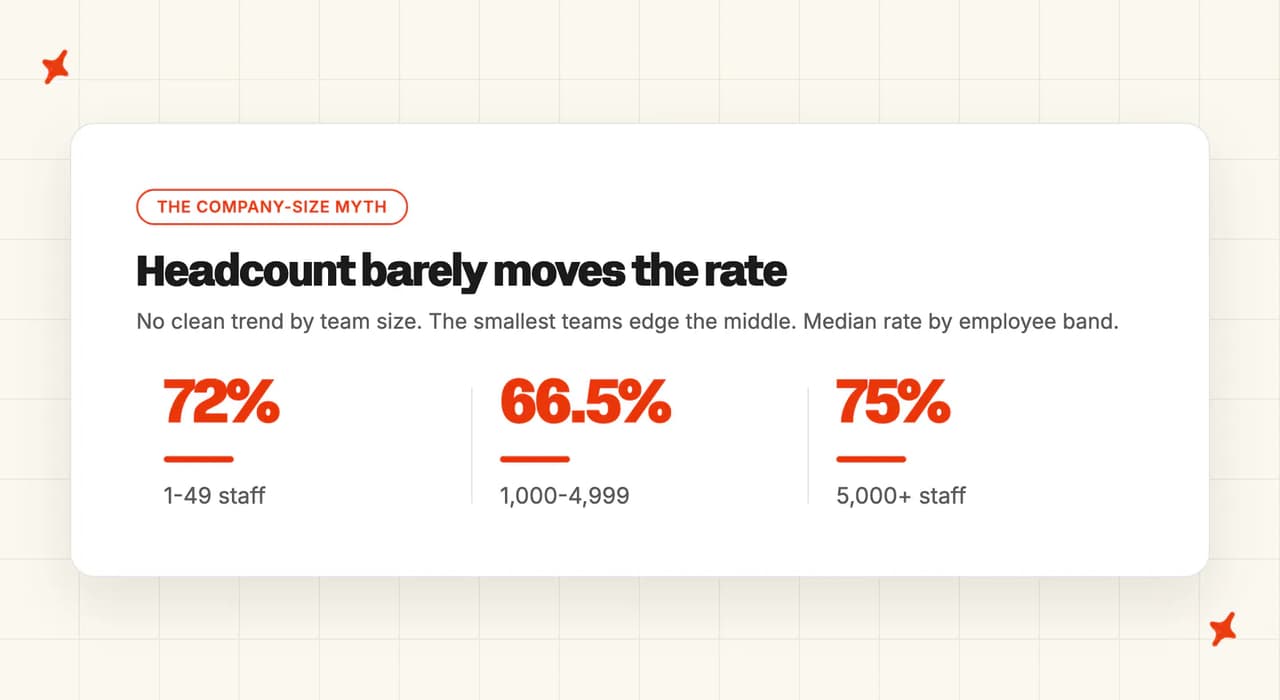
| Employees | n | Min | P25 | Median | Mean | P75 | Max |
|---|---|---|---|---|---|---|---|
| 1-49 | 48 | 15 | 52 | 72 | 68 | 85 | 95 |
| 50-199 | 50 | 20 | 55.2 | 70 | 66.5 | 80.2 | 94 |
| 200-999 | 50 | 15 | 51.1 | 70 | 65.2 | 80.2 | 98.3 |
| 1,000-4,999 | 22 | 26 | 56 | 66.5 | 63 | 70.2 | 90 |
| 5,000+ | 11 | 50 | 61 | 75 | 72.7 | 80 | 92 |
There is no clean trend here. The smallest companies (1 to 49 staff) post a 72% median, the largest (5,000+) post 75%, and the middle sags slightly.
If anything, small teams do marginally better, probably because they set up fast and have simpler products. The takeaway matches the revenue cut: stop blaming or crediting your headcount.
By vendor
This table is a map of what each vendor publishes rather than a quality ranking. Vendors choose which customers to feature, define "resolution" differently, and have very different sample sizes, so I'd read the range and read the n before reading anything into a single median.
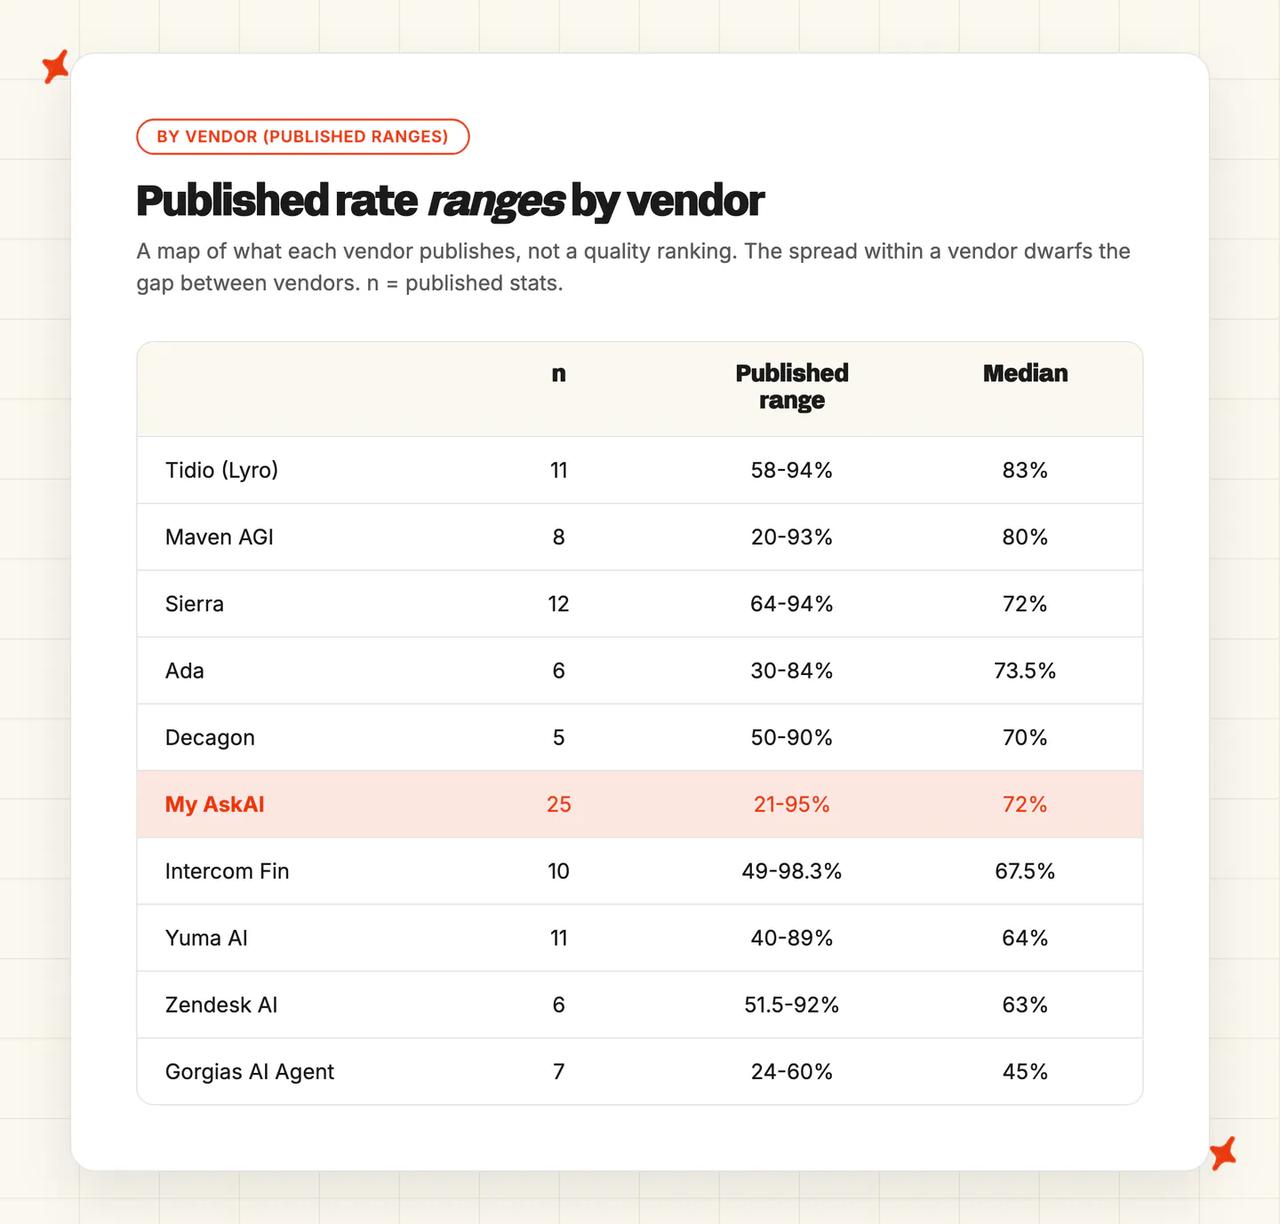
| Vendor | n | Min | Median | Max |
|---|---|---|---|---|
| Tidio (Lyro) | 11 | 58 | 83 | 94 |
| Maven AGI | 8 | 20 | 80 | 93 |
| Groove HQ / Helply | 7 | 50 | 78 | 91.4 |
| Sierra | 12 | 64 | 72 | 94 |
| Ada | 6 | 30 | 73.5 | 84 |
| Salesforce Agentforce | 7 | 40 | 70 | 85 |
| Decagon | 5 | 50 | 70 | 90 |
| Aisera | 5 | 65 | 70 | 81 |
| My AskAI | 25 | 21 | 72 | 95 |
| Intercom Fin | 10 | 49 | 67.5 | 98.3 |
| Yuma AI | 11 | 40 | 64 | 89 |
| Zendesk AI | 6 | 51.5 | 63 | 92 |
| Gladly (Sidekick) | 6 | 44.5 | 62.5 | 88 |
| HubSpot Breeze | 4 | 37 | 59 | 94 |
| Richpanel | 8 | 30 | 53 | 72 |
| DigitalGenius | 8 | 20 | 43 | 88 |
| Gorgias AI Agent | 7 | 24 | 45 | 60 |
Notice how wide most of the ranges are. Intercom Fin's published customers span 49% to 98.3%, and our own span 21% to 95%.
That spread is the real story. Within a single product, the difference between the best and worst deployment dwarfs the difference between products. The vendor you pick matters less than what you do with it.
(Single-customer vendors such as Netomi, Chatbase, Kapa, and Help Scout are left out of this table as benchmarks, because one published figure is an anecdote rather than a rate.)
Where our own deployments sit
I'll show our own numbers the same way, in aggregate, because a head-to-head "us versus them on rate" comparison would be exactly the apples-to-oranges mistake this whole report warns against.
Our own customer base averages 72% on a rolling basis, a little above the 70% field line, and on a strict resolution metric rather than a softer automation one. That average is fully transparent: it spans every deployment, from deliberately-low-by-design ones in the low 20s (like Sofar Sounds at 26%) up to 95%. We publish the low ones too, which most vendors don't.
The pattern inside our data matches the report, and setup drives the result. TravelJoy went from 24% on their previous AI to 80% with ours, and Edel Optics climbed from 25% to 79% after the team connected their User Data API.
Volume is not a ceiling either: one prop-trading platform on our books runs at 73% across roughly 105,000 tickets a month.
And a low rate can be a deliberate choice. Sofar Sounds sits at 26% by design, because they route most tickets to humans on purpose, and they still post 85% AI CSAT.
For the record, we count a conversation as resolved when the AI handled it without escalating to a human. It is a deliberately simple definition, and it holds up because we make escalation genuinely easy. A customer can ask for a person at any time, and the AI hands off when it cannot answer, detects frustration, or hits a topic set for escalation.
We don't claim to know an issue was truly solved without the customer confirming it, and we don't invent a way to pretend we do.
How to read your own number
Before you celebrate or panic about your resolution rate, normalize it. Here is the whole process, and it takes less than an afternoon.
- Confirm which metric your vendor reports. Resolution, automation, deflection, and containment are different events. Find out which one your dashboard shows before you compare it to anyone (we get asked to compare numbers that were never comparable in the first place). About 30 minutes of reading docs.
- Benchmark against your industry row. Use the by-industry table above instead of the global median. A 66% rate means different things in education and in retail (15 minutes, tops).
- Always pair the rate with CSAT and reopen rate. A resolution rate on its own is uninterpretable, because a bot can "resolve" tickets by frustrating people into giving up. In our data that pairing is the single most common way a good-looking rate hides a bad experience.
- Test it on your own tickets. This is the only number that is truly yours. A free trial or pilot on a slice of your real volume (yes, your own messy tickets) beats any benchmark on this page.
- If the rate is low, audit the setup levers. Look at what the AI couldn't answer, which tools and APIs aren't connected yet, and whether your escalation rules are forcing handoffs. That is where the lift lives, and it is work you control. While you're choosing, I'd favor a tool that makes climbing easy, because today's number is only a starting line.
How to read these numbers
A few caveats keep this report straight, and (in our experience) they matter as much as the headline.
A higher rate is not always better. In regulated or high-judgment queues, like fintech disputes or medical questions, a fast handoff to a human is often the correct outcome. A lower automation rate there can mean the AI is behaving exactly as it should.
A high rate can also be inflated. If an AI never discloses that it is an AI and never offers an easy route to a human, "resolution" quietly becomes "the customer gave up". I'd argue a number is only as trustworthy as the escalation path behind it.
And remember the two structural caveats from the top. Published vendor figures are best-case, so take the field average with a grain of salt (the true number across all deployments is likely below 70%).
Small samples, meaning any cell here with an n of 1 to 3, are directional only. This is a 2026 snapshot, and these numbers will climb as models and setups mature.
The takeaway
So what is a good AI resolution rate? Around 70% is the industry's center of gravity, and to my mind that is the least useful sentence in this whole report. The useful version: the number a vendor quotes you is best-case, your result depends far more on your setup than on your industry or your size, and the only rate that means anything is the one you measure on your own tickets.
Pick a tool for its headroom rather than the figure on its homepage. The gap between a good deployment and a bad one of the same product is bigger than the gap between products, and closing that gap is mostly work you control.
If you want to go deeper on the pricing consequences of all this, our breakdown of per-conversation versus per-resolution pricing is the companion piece, since the meter you choose decides whether a rising resolution rate helps you or bills you. You can try My AskAI on your own tickets to get your real number.
And anyone is welcome to cite this dataset. We built it to be the benchmark the industry has been missing.
FAQs
What is a good AI resolution rate?
Across 195 real deployments and 38 vendors, the median is 70%, with half the field between 56% and 80%. "Good" depends on your metric, industry, and setup. We'd treat 70% as the line to clear, 80%+ as strong, and anything below 50% as a sign your setup has room to improve rather than a verdict on the tool.
What resolution rate should I expect from AI customer support?
Expect a starting point well below your eventual ceiling. Many deployments begin at 20% to 40% before the knowledge base, integrations, and escalation rules are tuned, then climb past 70% with work. The real answer is to run a pilot on your own tickets, because your mix and setup matter more than any benchmark.
What is AI resolution rate?
AI resolution rate is the share of customer conversations an AI agent handles to the end without a human taking over. We count a conversation as resolved when the AI handled it without escalating to a person, and that only holds up because reaching a person is easy. Every vendor defines "resolved" a little differently, so check the definition before you compare two numbers. Across 195 rated deployments and 38 vendors, the median is 70%.
What's the average AI resolution rate across the industry?
The median across our dataset is 70% and the mean is 66.6%. We lead with the median because a handful of very high and very low deployments skew the average. Bear in mind these are mostly self-selected published figures, so the true average across all deployments is probably a little lower.
Why do AI vendors report such different resolution rates?
Mostly because they measure different things. A resolution metric runs a 72.5% median in our data, a softer automation metric runs 61%, and containment lower still. Two vendors doing equally good work can post numbers 12 points apart purely from how they define the metric, so always check the definition before comparing.
Does company size affect AI resolution rate?
Barely, and that genuinely surprised us too. Median rates stay in a 65% to 72% band across every revenue tier from under $1M to over $1B, and across every employee tier from under 50 staff to over 5,000. Your setup and your industry drive the result, and your headcount does not.
Which industries get the highest AI resolution rates?
Education (81.5% median), government and non-profit (81%), media (80%), and travel (78.5%) sit at the top, because their tickets are repetitive and lower-stakes. Telecom, manufacturing, food and beverage, and retail sit lower. In our reading the driver is how automatable the typical ticket is rather than the sector's sophistication.
Is a higher AI resolution rate always better?
No, and I'd gently push back on the assumption. In regulated or high-judgment queues, escalating to a human is often the right call, so a lower rate can be correct. A rate without CSAT can also hide a bot that resolves by frustrating people into giving up, which is why we always read resolution rate alongside CSAT and reopen rate.
How is AI resolution rate different from deflection or automation rate?
Resolution measures whether the issue was actually solved end to end. Deflection only measures that a contact didn't reach a human, and containment that it stayed in-channel, and neither proves the problem was fixed. Automation is a looser catch-all for work the AI touched, and we treat all of them as different events on the customer journey, which is why their benchmark numbers differ.