Does the AI Resolution Rate Hold at 30,000+ Tickets a Month?
148 of 195 published AI resolution rate benchmarks never say how many tickets they cover. We cut the 47 that do, and high volume shows no sign of a drop.
Summarize with AI
You have read the headline benchmark, and the obvious question is whether it survives your volume. At 30,000 tickets a month staffing is harder and reporting is slower, and a rate measured across a few thousand tickets reads like a number from a smaller business.
Published rates rarely settle that doubt. Each vendor publishes a win, and hardly any of them name the ticket volume behind it. So we cut our corpus by disclosed monthly volume and put both bands side by side, with the row counts attached.
AI resolution rate by ticket volume and by disclosure, at a glance
The first two cuts below split the disclosing rows at 30,000 tickets a month, and the other two split the published record by whether it states a ticket volume at all. We never quote one of these medians without the row count next to it.
| Cut of the 195 rated deployments | Rows (n) | Median AI resolution rate |
|---|---|---|
| 30,000 tickets a month or more | 9 | 77.0% |
| Under 30,000 tickets a month | 38 | 74.5% |
| Discloses a ticket volume | 47 | 75.0% |
| Discloses no ticket volume | 148 | 70.0% |
How did we measure this?
What a rate is worth depends on its method. Ours comes down to which rows we let in, how we made them comparable, and what we refused to guess at.
Vendors count different things. Some publish a resolution rate, some an automation rate, some a deflection or containment rate, and the numerators differ underneath. So we put every rate on the same scale before we compare them, and none of that changes what each vendor was counting. Notch, a competitor with its own benchmark page, makes the same point:
"The percentage is the starting point. The definition is the substance."
In our own rows, a conversation counts as resolved when the AI handled it without escalating to a human.
The volume field is the one this post turns on. A row counts as disclosing volume when the publishing source states a ticket or conversation count for a set period. We turn that count into a monthly estimate (a weekly figure times 4.33, a yearly one divided by 12), and 47 of the 195 rated rows have one. A total with no period attached, or a phrase like "tickets doubled", I left as no disclosure, because there is no month to divide it by.
Where this page gives a middle half, we left the median itself out when we worked the quartile edges. Put it back in and the edges move by about a point.
I keep three things about the method in mind for every number on this page. The data is aggregate, so it shows where the field is and never stages one vendor against another. Vendors define the metric differently, which means two figures that look equal can be counting different conversations. Published competitor figures are self-selected wins (a vendor picks which deployment to write up), so they mark the top of the field's range.
Lorikeet is explicit about the scope of the published averages it lists:
"Every average is computed across a vendor's own customer base"
The fourth is about us. Of the 47 volume-disclosing rows, 22 are our deployments; strip those out and 25 of the remaining 170 rated rows disclose volume, fewer than one in six.
Our rows are over-represented in this finding, far above our share of the corpus.
Do published AI resolution rates say how many tickets they cover?
Before cutting the data by volume, look at how many rows have a volume to cut by.
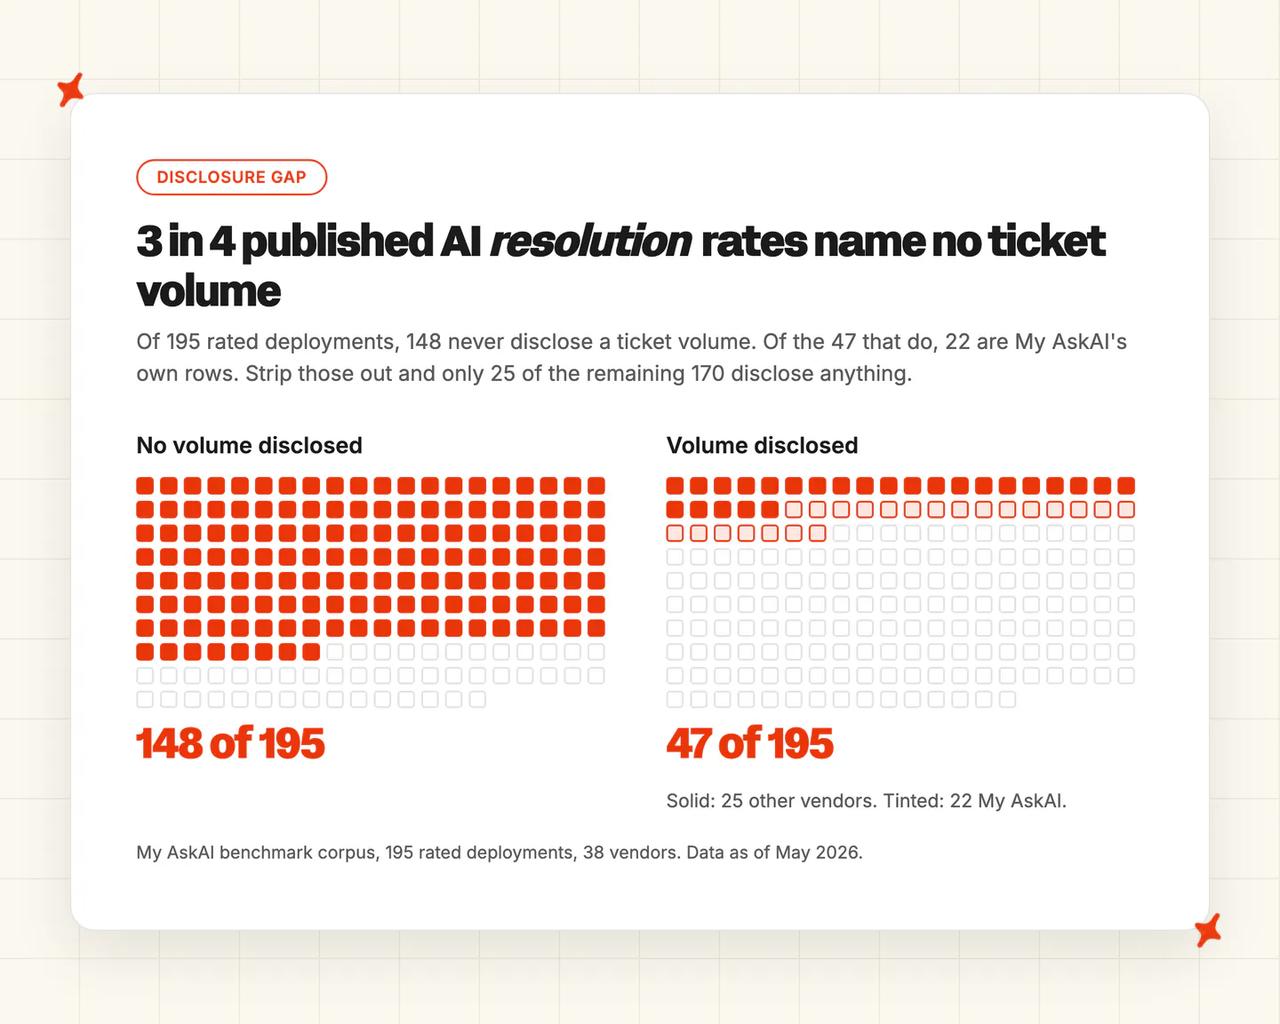
The 148 rows with no volume estimate have a median of 70.0%, against 75.0% for the 47 that do disclose. I read that 5 point gap as a disclosure habit. Showing the ticket count is easier when the number is good, so the rows that keep it quiet sit lower.
Take our rows out and the scarcity is starker: 25 of the 170 rated rows published by everyone else state a ticket volume.
A rate with no volume behind it might be three years across millions of tickets. It might just as easily be a two-week pilot on one help center topic. One question separates them: across how many tickets a month, and over what window? I ask that on every vendor call I sit in on.
The large numbers beside published rates usually measure the wrong thing. A vendor's corpus size counts conversations across its whole customer base, the way Notch rests its benchmark on more than 20 million conversations. Your operation is one account inside a number like that, and so is every deployment we run. Fin footnotes its benchmark page the same way:
"Based on 110M+ Fin conversations across 12,000 + customers and 15 industries."
We publish the monthly volume beside each of our own rates, which is why most of our rows sit on the disclosing side of that 148-to-47 split.
Does the AI resolution rate hold at 30,000+ tickets a month?
The headline benchmark could not answer this question. Split the 47 rows that disclose a volume at the 30,000-tickets-a-month line and see whether the two halves separate.
Both bands are below, with the number of rows behind each one.
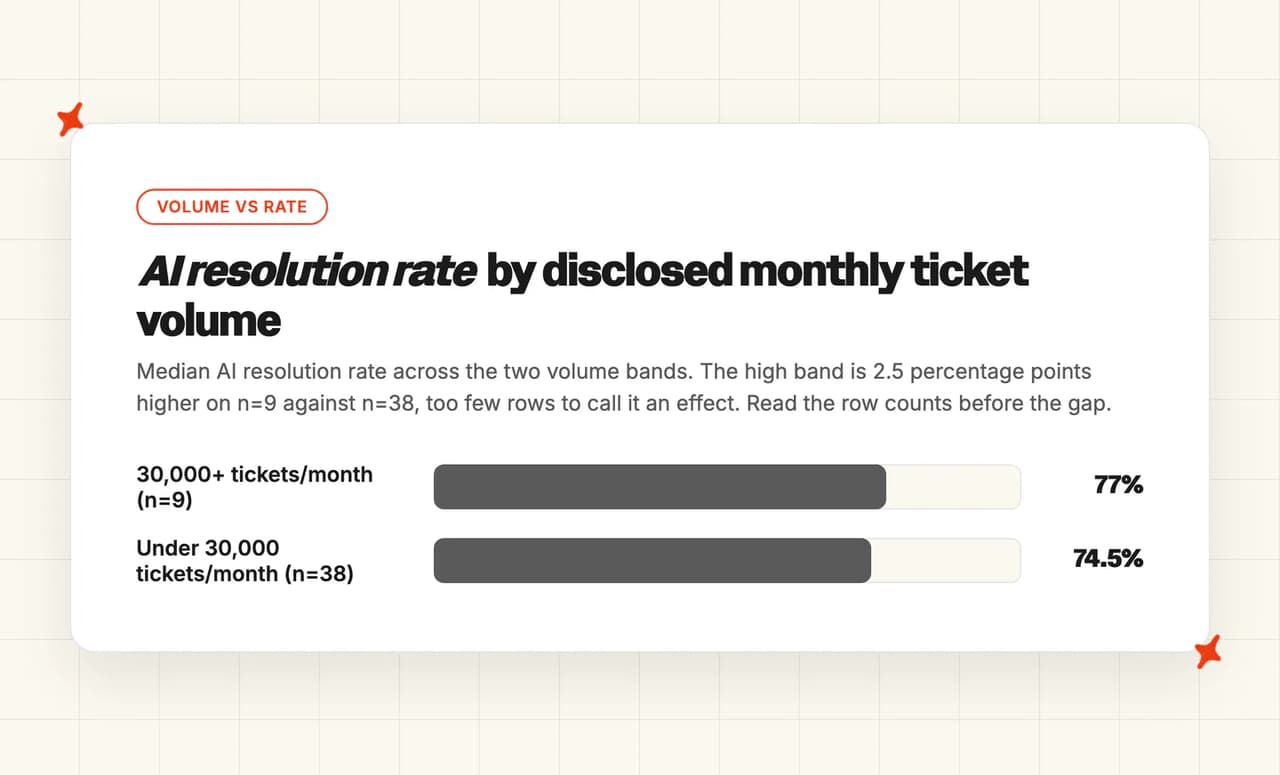
| Monthly tickets (our estimate) | Rows (n) | Median AI resolution rate | Middle half | Range |
|---|---|---|---|---|
| 30,000 or more | 9 | 77.0% | 64.5% to 84.5% | 47% to 91% |
| Under 30,000 | 38 | 74.5% | 62.75% to 82.5% | 21% to 95% |
Two and a half points separate them, on 9 rows against 38, and the higher median belongs to the high-volume band. No set of nine rows is big enough to average a whole scale band, ours included.
Finer cuts scatter. Under 10,000 tickets a month is 76.0% (n=31), and 10,000 to 30,000 is 70.0% (n=7). From 30,000 to 100,000 it is 83.0% (n=4), and at 100,000 or more it is 70.0% (n=5). Across the four small bands the median falls, rises and falls again, and each band is too thin to draw a line through.
We ran the same cut again with our rows taken out, to see what the rest of the published record says on its own. The 30,000-or-more band stays at 77.0% (n=7), and the band below it climbs to 80.0% (n=18). The high-volume band goes from 2.5 points ahead to 3 points behind, depending on whose rows are in.
Our AI resolution rate benchmark study already reports that company size and revenue band barely move the rate, and headcount and revenue are not ticket volume. The published field answers the scale question with deployment maturity and integration depth, and Lorikeet bands mature deployments at roughly 50% to 76% on the same logic. Neither of those pages cuts by volume.
We run deployments at both ends of this range. On the chart, read the row count printed on each bar before you read the gap between them.
What do the nine deployments at 30,000+ tickets a month actually look like?
A median hides the rows underneath it, and nine rows are a small enough set to print whole.
We have published one deployment at this scale in full: a trading platform now resolving 73% of its ~105,000 monthly tickets (64% in the May 2026 snapshot this post's data comes from), in our high-volume AI customer support case study. Nine rows give you the band around it.
The nine are below, sorted by our monthly volume estimate, with nothing attached but industry and the metric family the source used.
| Monthly tickets (our estimate) | Industry | Metric family | AI resolution rate |
|---|---|---|---|
| 1,000,000 | Financial services | Resolution | 70% |
| 166,667 | Travel | Resolution | 77% |
| 138,560 | SaaS | Resolution | 85% |
| 125,420 | Retail | Automation | 65% |
| 105,000 | Financial services | Resolution | 64% |
| 70,000 | Financial services | Resolution | 91% |
| 70,000 | Media | Resolution | 82% |
| 40,000 | Financial services | Automation | 47% |
| 30,000 | Financial services | Resolution | 84% |
The band spans 33 times in volume, so a single 30,000+ label hides a wide range. Almost all the variation sits inside the band rather than between the bands. I went in expecting the opposite.
The metric families are mixed too: seven of the nine are resolution figures and two are automation figures. Resolution counts the conversations the AI finished. Automation counts every conversation it touched. Our post on containment, deflection and resolution has the full definitions.
The chart below plots each of the nine rows as its rate against its monthly volume estimate. The dots scatter down the whole chart.
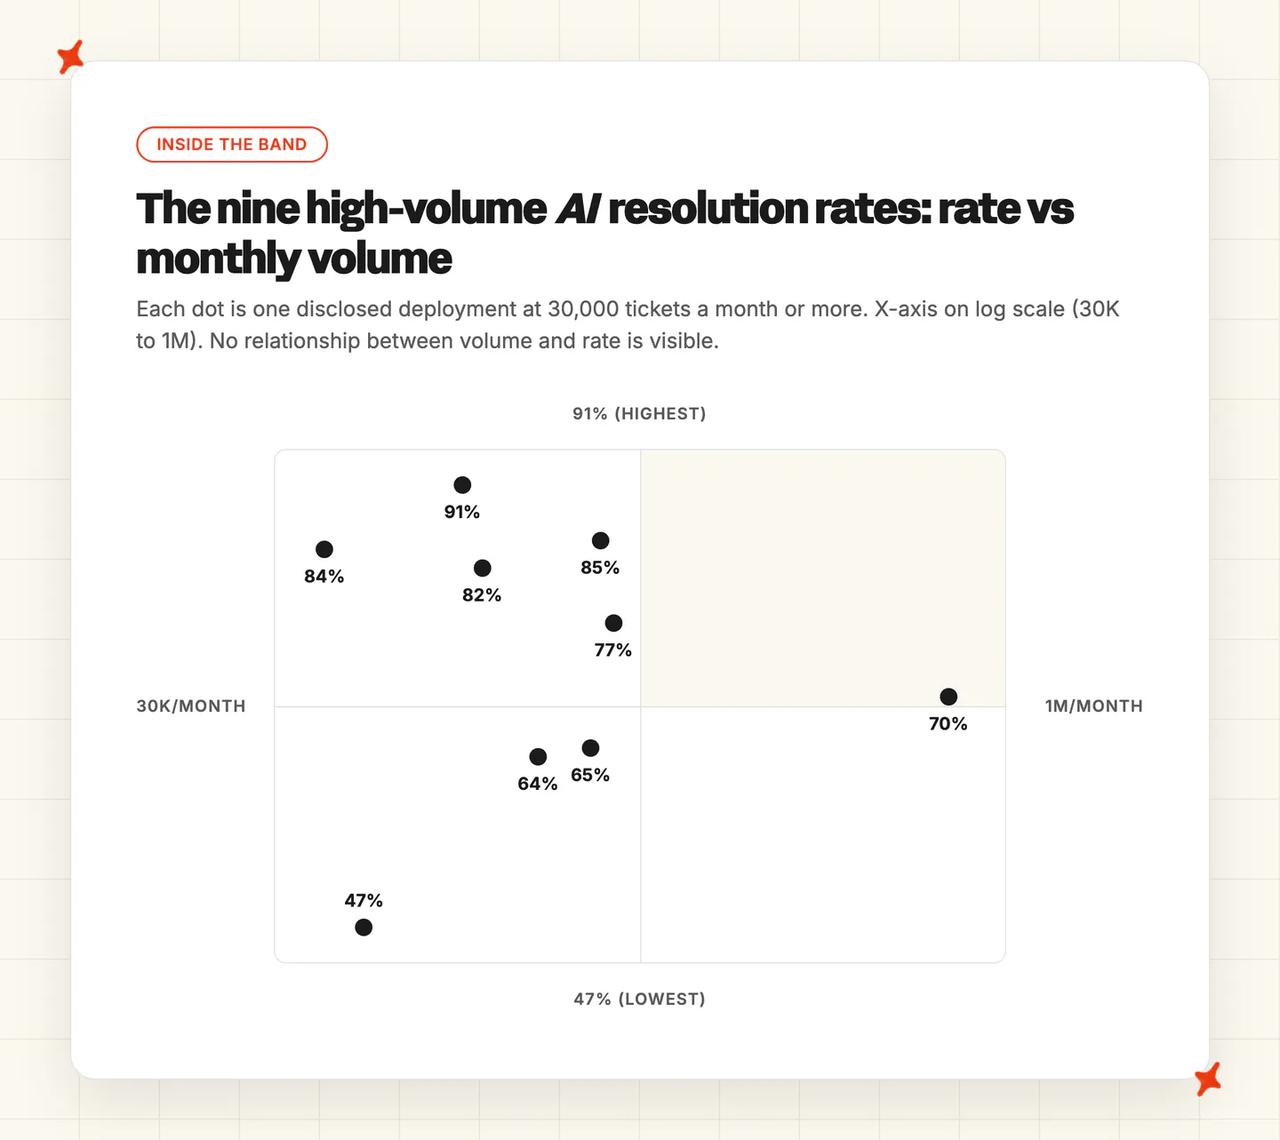
Two of the nine rows are ours. The other seven come from vendors who published a volume alongside a rate.
Most of the high-volume rows are financial services, so what does that do to the number?
Nine rows do not cover five industries evenly. Look at which businesses put this number there.
Break the nine rows down by industry and the band stops looking like a cross-section of the market.
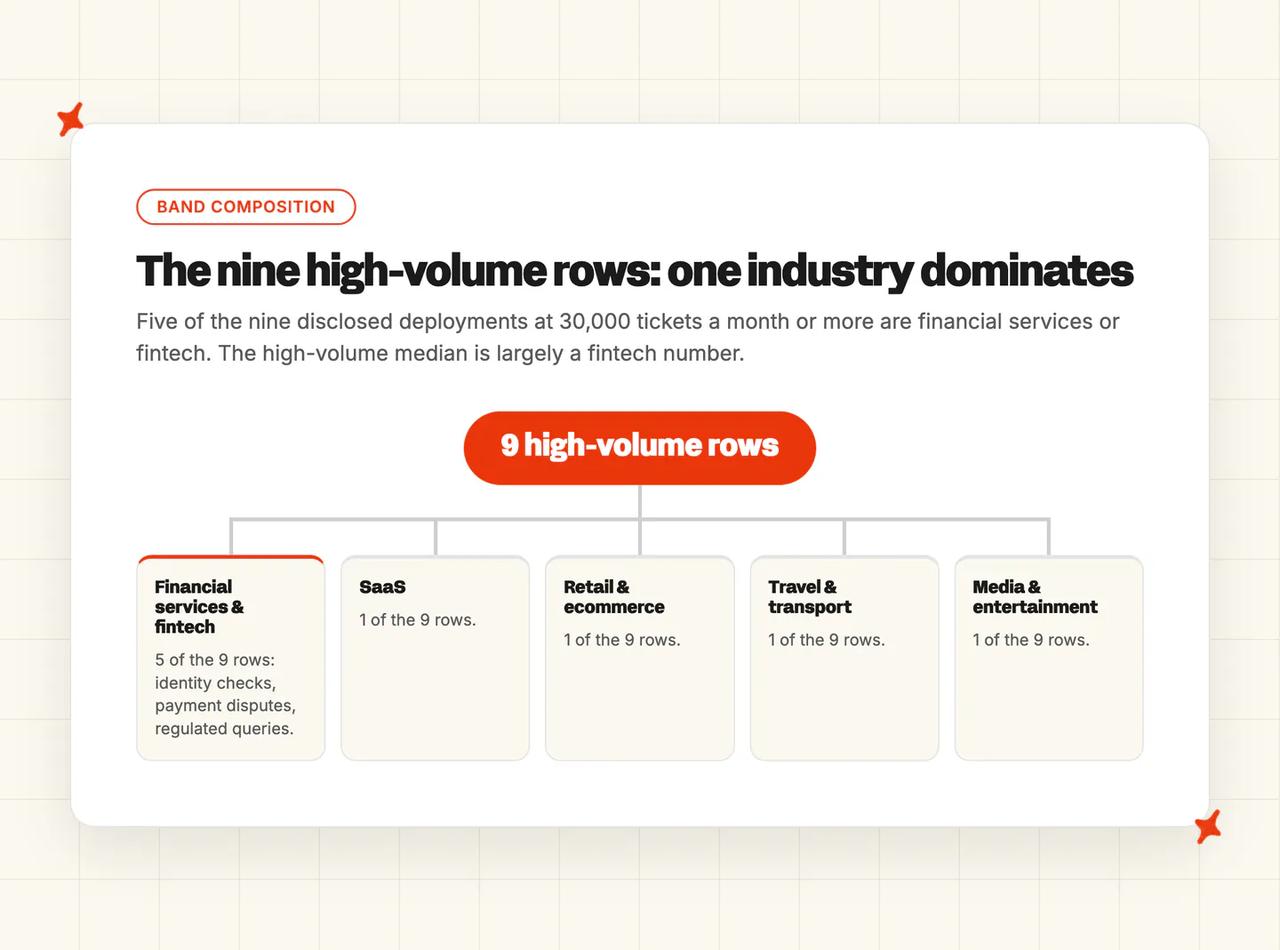
- Financial services and fintech - 5 rows of the 9
- SaaS - 1 row
- Retail and ecommerce - 1 row
- Travel and transport - 1 row
- Media and entertainment - 1 row
Ticket mix moves a rate, and fintech support runs the heaviest mix we deal with: identity checks, payment disputes, regulated answers that have to be right. So a median built mostly from fintech rows is telling you about fintech tickets. Aissist reaches a wider version of the same caution about what a published figure covers:
"The vendor-claimed vs. field-aggregate gap is structural."
Consumer-facing businesses are well represented in the corpus overall, so I cut those too: retail and ecommerce, health and wellness, travel and transport, media and entertainment, and food and beverage together make 87 rated rows at a 70.0% median. Only 19 of those 87 disclose a volume, and only 3 are at 30,000 tickets a month or more.
Three rows cannot hold up a consumer benchmark at high volume. Our benchmark study publishes the industry cut across the full corpus, where the row counts are large enough to support it.
If you run consumer retail at 30,000 tickets a month or more, treat these nine rows as context. Use the 47% to 91% spread as the range to expect, and read our industry cut for the one you run in.
More than half of this band is one industry. Treat it as a fintech number with four other industries attached.
What does this mean for your team?
A benchmark sets a target, and it tests what a vendor tells you. I think this data is most useful for the testing.
When a vendor puts a percentage in front of you, these are the three things I ask.
- Which metric is this? - Seven of our nine high-volume rows are resolution figures and two are automation figures, and they count different things.
- Across how many tickets a month, and over what window? - 148 of 195 published rates never answer this, so asking it puts you ahead of three quarters of the field.
- In which industry and ticket mix? - Five of the nine high-volume rows are financial services, so any high-volume median we show you carries that mix inside it.
To put your own number against these bands, export last month's conversations and let whichever AI tool you already use group them by whether a human touched them. That gives you a figure on the same definition the corpus uses.
At this scale, a lower number can be the right one. A regulated or high-judgment ticket mix should escalate more, and a rate read on its own tells you nothing about whether those customers came back. Read it with CSAT and reopen rate beside it, as our post on AI customer service KPIs sets out.
Which tool to run at this volume is a separate question, and our roundup of the best AI customer service tools for high volume covers it.
Our own rate is 72%, resolved on a rolling 30-day basis across My AskAI's whole customer base. It is one number from one book of business, measured at one point in time, and the same caveats I put on everybody else's numbers apply to it. The ceiling you reach depends on your setup.
FAQs
Does AI resolution rate drop at high ticket volume?
Not in this corpus. Median AI resolution rate is 77.0% across the 9 disclosed deployments at 30,000 tickets a month or more, against 74.5% across the 38 under that line. The high band sits 2.5 points higher, and 9 rows are too few to call that an effect, so I treat the finding as directional: volume shows no sign of pulling the rate down.
What AI resolution rate do companies with 30,000+ tickets a month actually get?
Across the 9 disclosed deployments at 30,000 tickets a month or more, the median is 77.0%, the middle half is 64.5% to 84.5%, and the full range is 47% to 91%. Those nine rows span 30,000 to 1 million tickets a month, so the label covers a wide range of businesses. Treat the spread as the range to expect and the median as a reference point, then read it beside our comparable band below 30,000, which is at 74.5% on 38 rows.
Do published AI resolution rates say how many tickets they cover?
Mostly not. 148 of the 195 rated rows in our corpus have no ticket-volume estimate at all, which is three quarters of the published record. Of the 47 that do disclose a volume, 22 are our deployments, leaving 25 disclosing rows out of the 170 published by everyone else. A published percentage with no scale attached is hard to act on, so we publish ours with the ticket volume next to it.
Is AI resolution rate different for enterprise support teams than for small ones?
On the volume evidence, no. The 9 disclosed deployments at 30,000 tickets a month or more have a 77.0% median and the 38 below have 74.5%, and four finer bands from under 10,000 tickets a month to 100,000 or more move up and down with no trend, on row counts of 4 to 31. The published field answers "enterprise" with deployment maturity and integration depth. Company size and revenue band are separate cuts, and our AI resolution rate benchmark study publishes both across the full 195 rated rows.
Autonomous resolution or ticket deflection: which one is in these numbers?
Mostly autonomous resolution. Of the nine high-volume rows, seven are resolution-family figures and two are automation-family figures, and no deflection-family row appears in the band at all. Across the whole corpus the families are resolution 108, automation 52, deflection 17, self-serve 9, containment 6, and one-touch or first-contact resolution 3. Which family a figure comes from changes what the percentage means, and our posts on containment versus deflection versus resolution, on autonomous resolution and on deflection rate set out what each one counts.